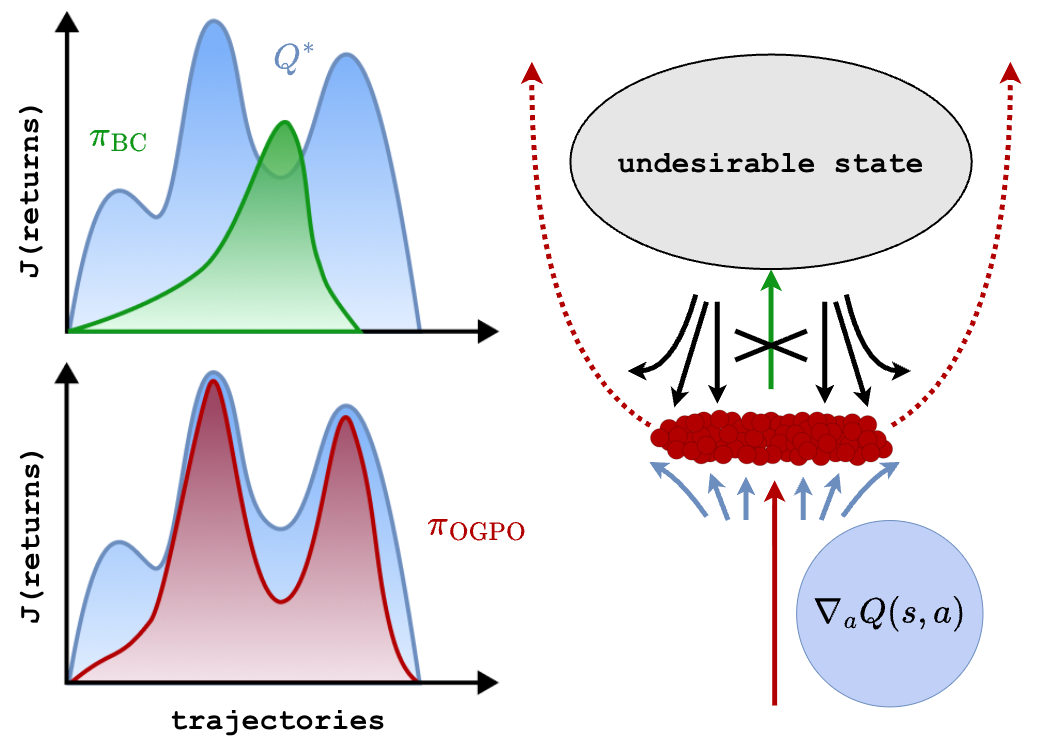
OGPO connects off-policy value learning with full-policy updates in the denoising process. Figure from the OGPO project.
Learning beyond demonstrations
Diffusion and flow policies can learn useful behaviors from demonstrations, but improving them through robot interaction is expensive. Off-Policy Generative Policy Optimization (OGPO) finetunes the complete generative policy while reusing past experience through off-policy critics.
How it works
Learn from experience. Train a critic using transitions collected in the environment and stored in a replay buffer.
Evaluate generated actions. Sample denoising trajectories and use the critic’s value as their terminal reward.
Update the full policy. Apply a modified PPO objective across the generative process to improve the actions it produces.
We study this approach across multi-task manipulation, high-precision insertion, and dexterous control. The paper and project website cover the experiments, stabilization techniques, and limitations.